unsafe.ltd

asera

Agentic security testing for your code and your running systems.

A team of AI agents reads your source, maps the live application and proves what it finds. Here is what that looks like.

Request an Asera demo

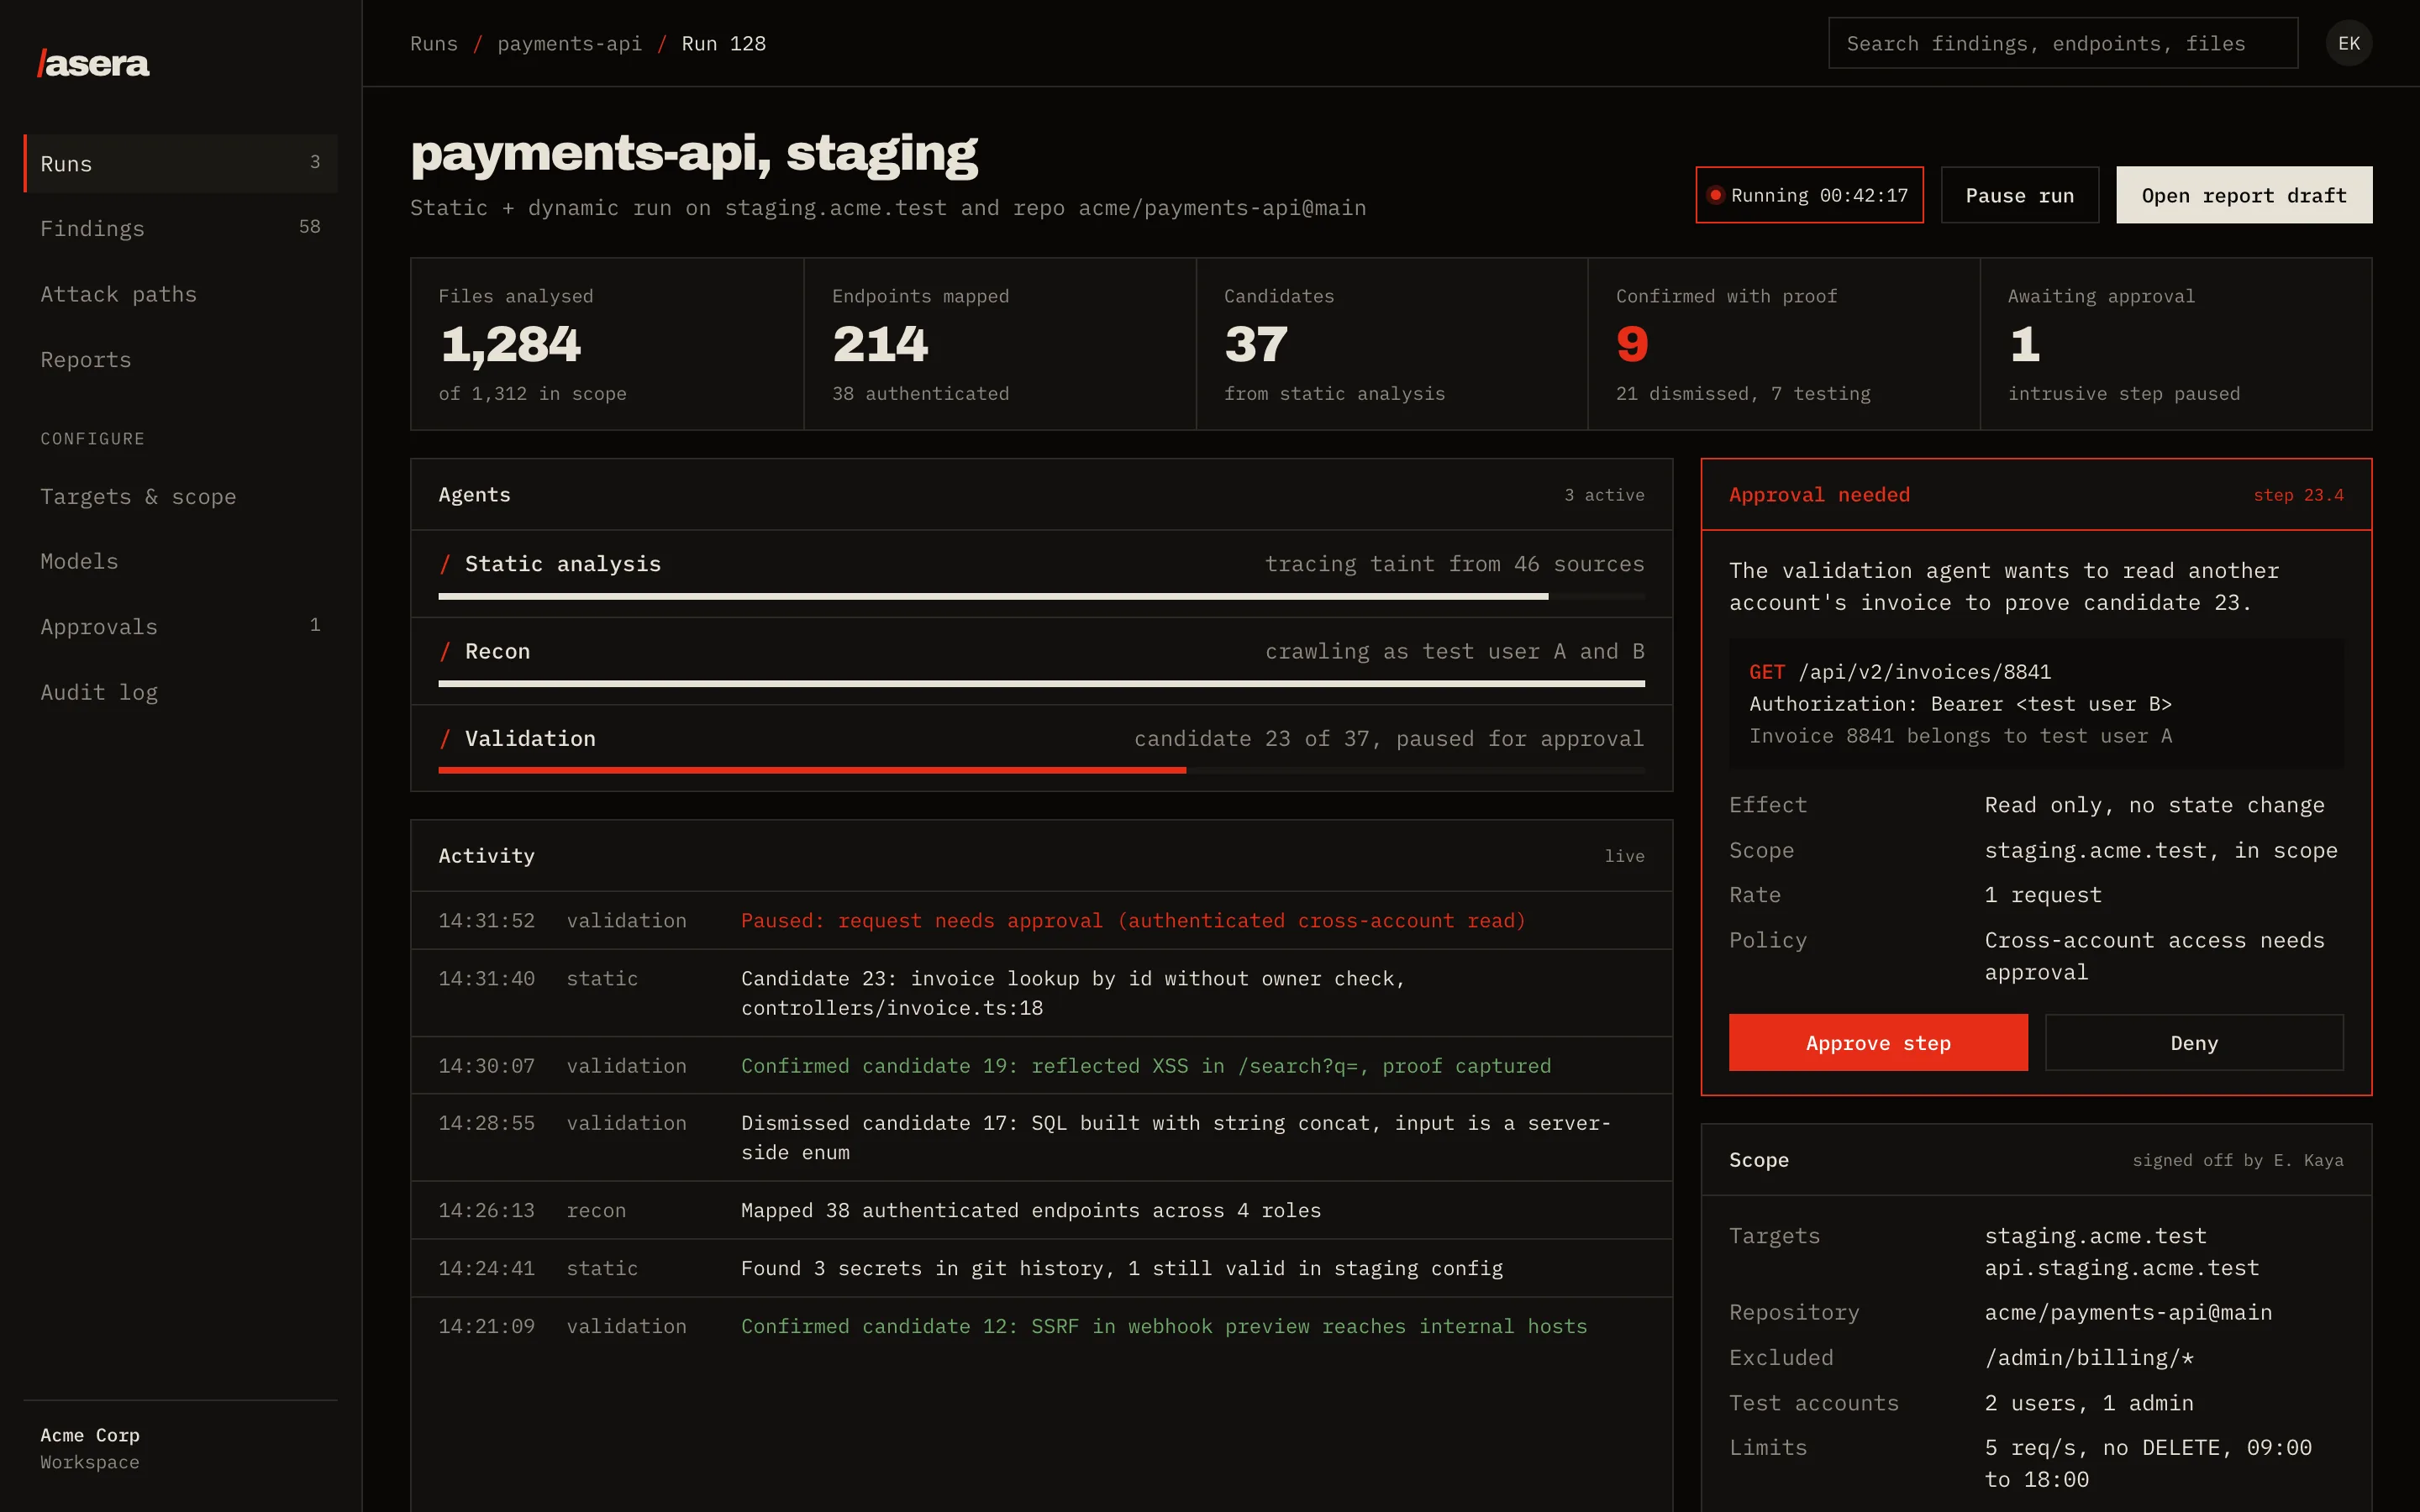
Watch the run. Approve the risky steps.

Agents for static analysis, recon and validation work in parallel. Anything intrusive, like reading another account's data, pauses until a person approves it.

  • Live progress for every agent
  • Every step logged with who approved it
  • Scope and limits visible for the whole run
Asera run screen: three agents working on payments-api, an activity log, and an approval request for a cross-account read

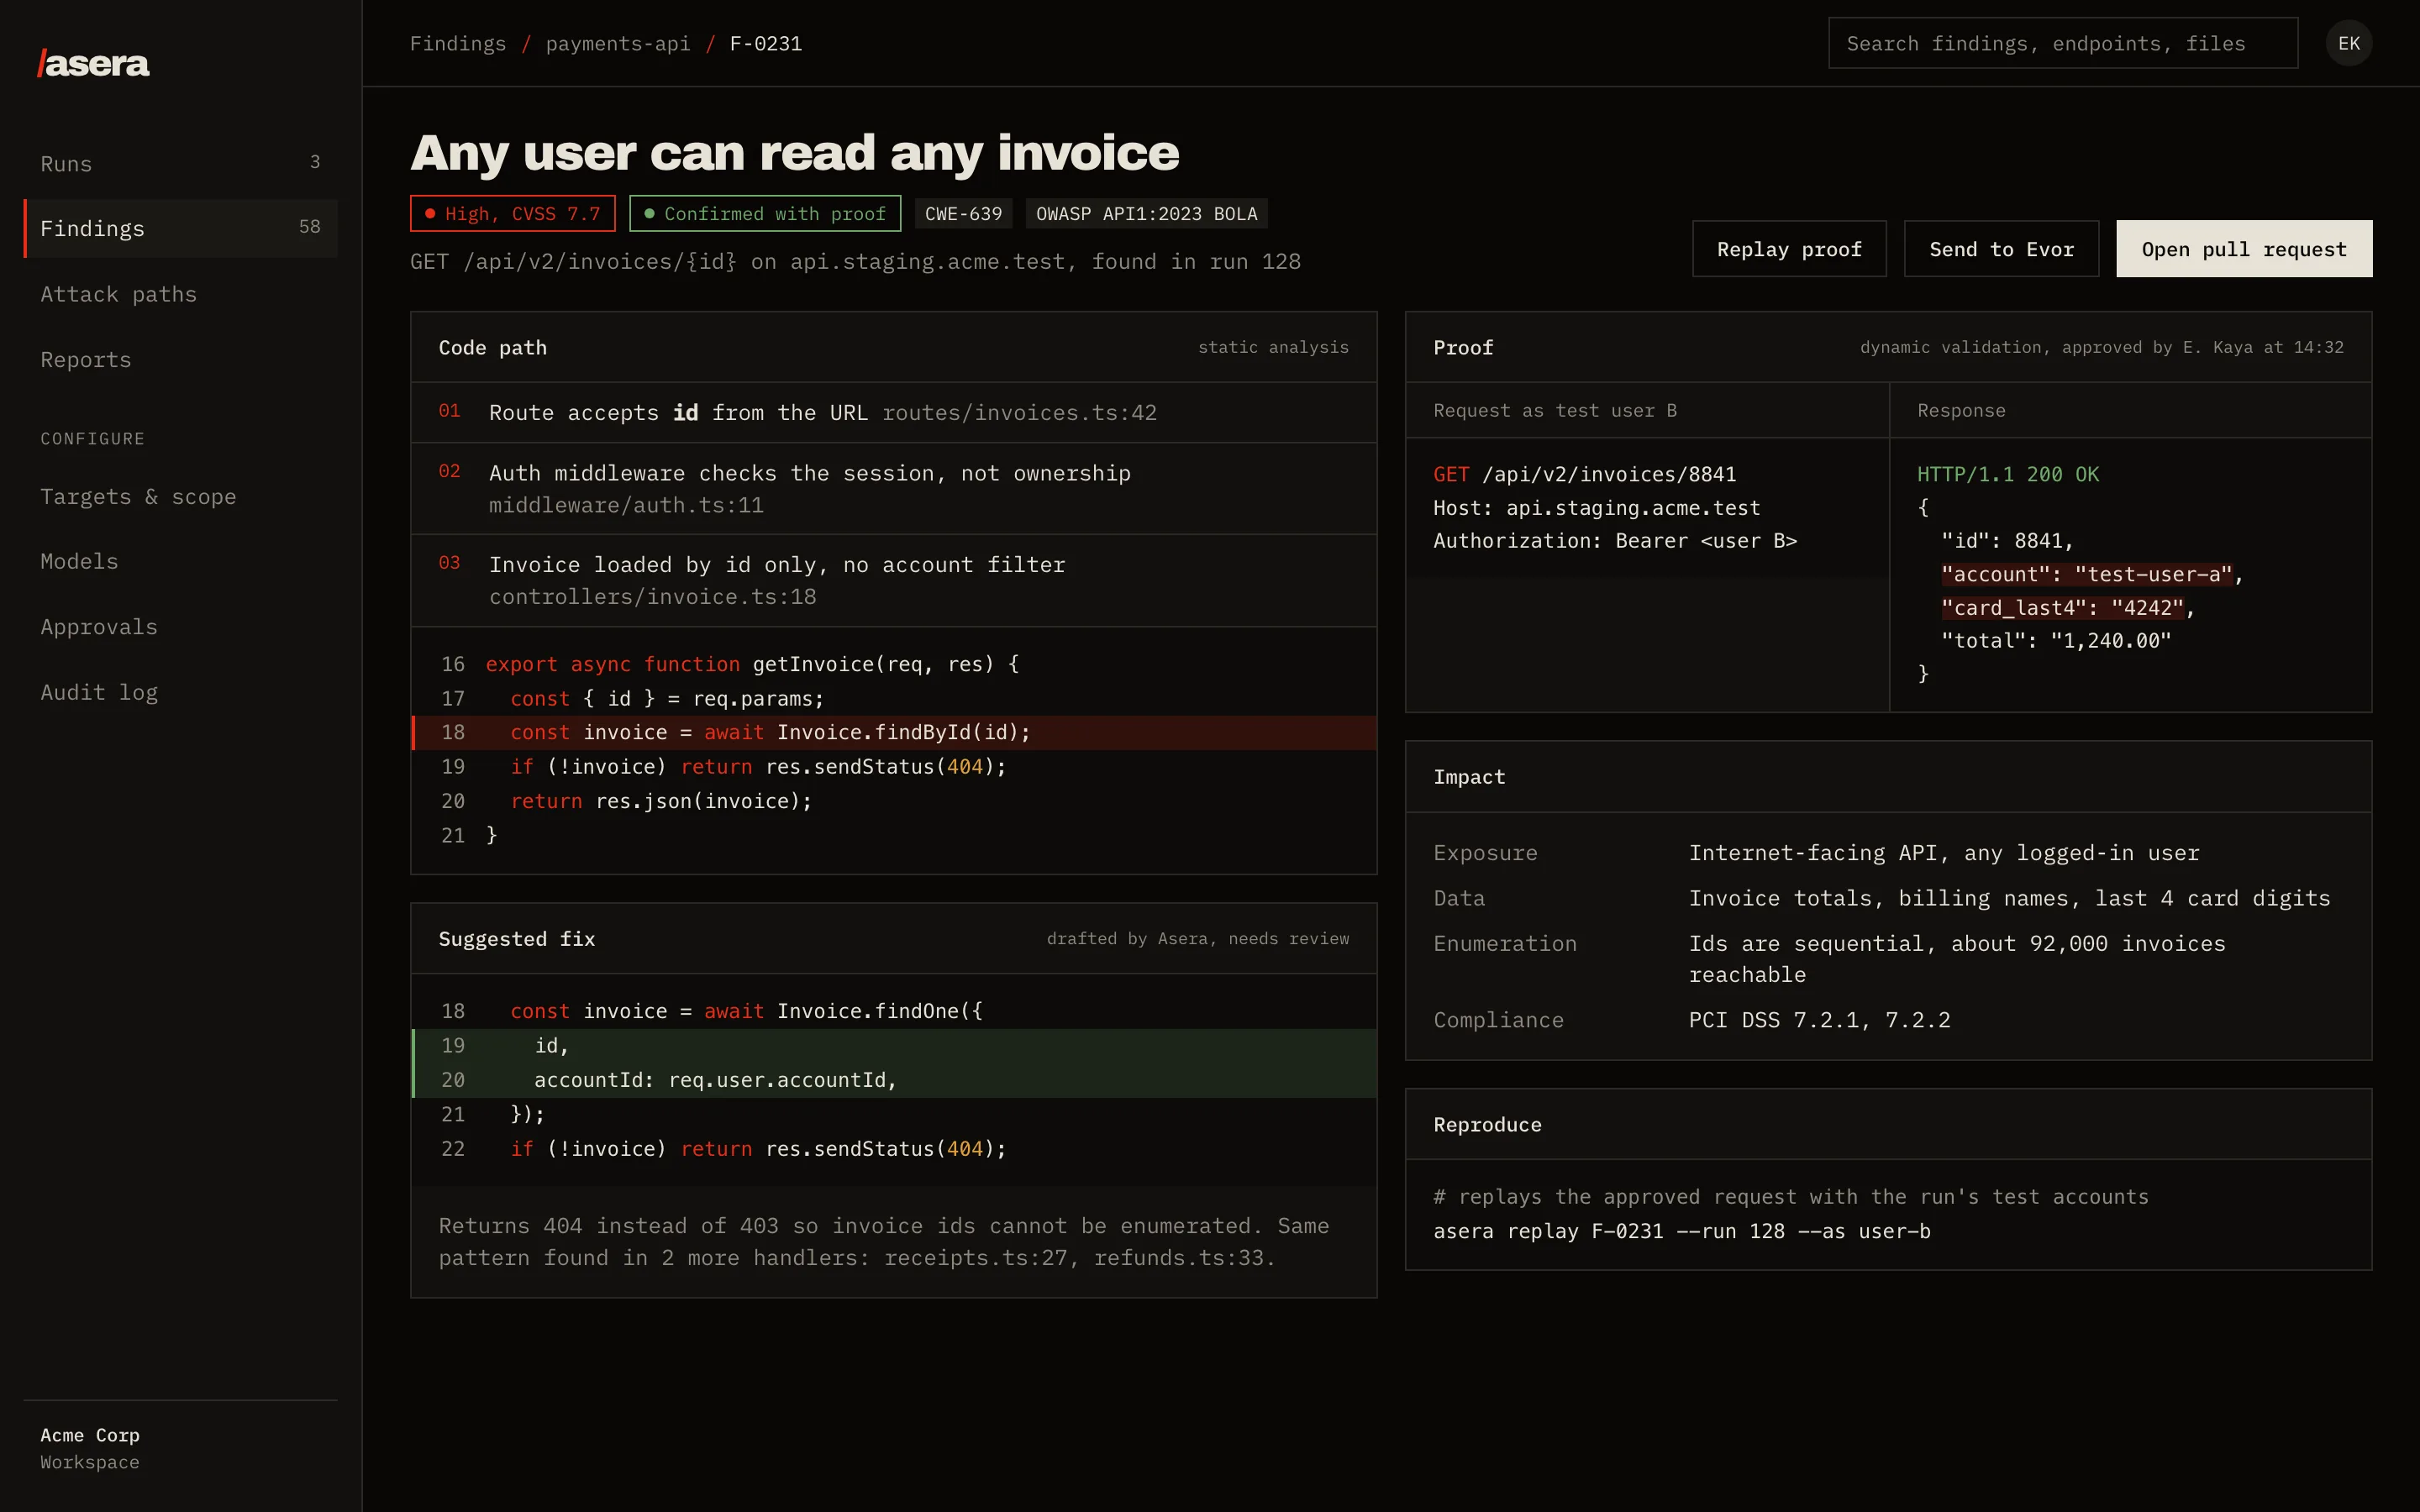
Findings with proof, not guesses.

Each confirmed finding shows the code path that causes it, the request and response that prove it, and a drafted fix you can review.

  • Mapped to CWE, OWASP and PCI DSS
  • Replay the proof with one command
  • The same flawed pattern is flagged across the codebase
Asera finding screen: broken object level authorization with code path, request and response proof, and a suggested patch

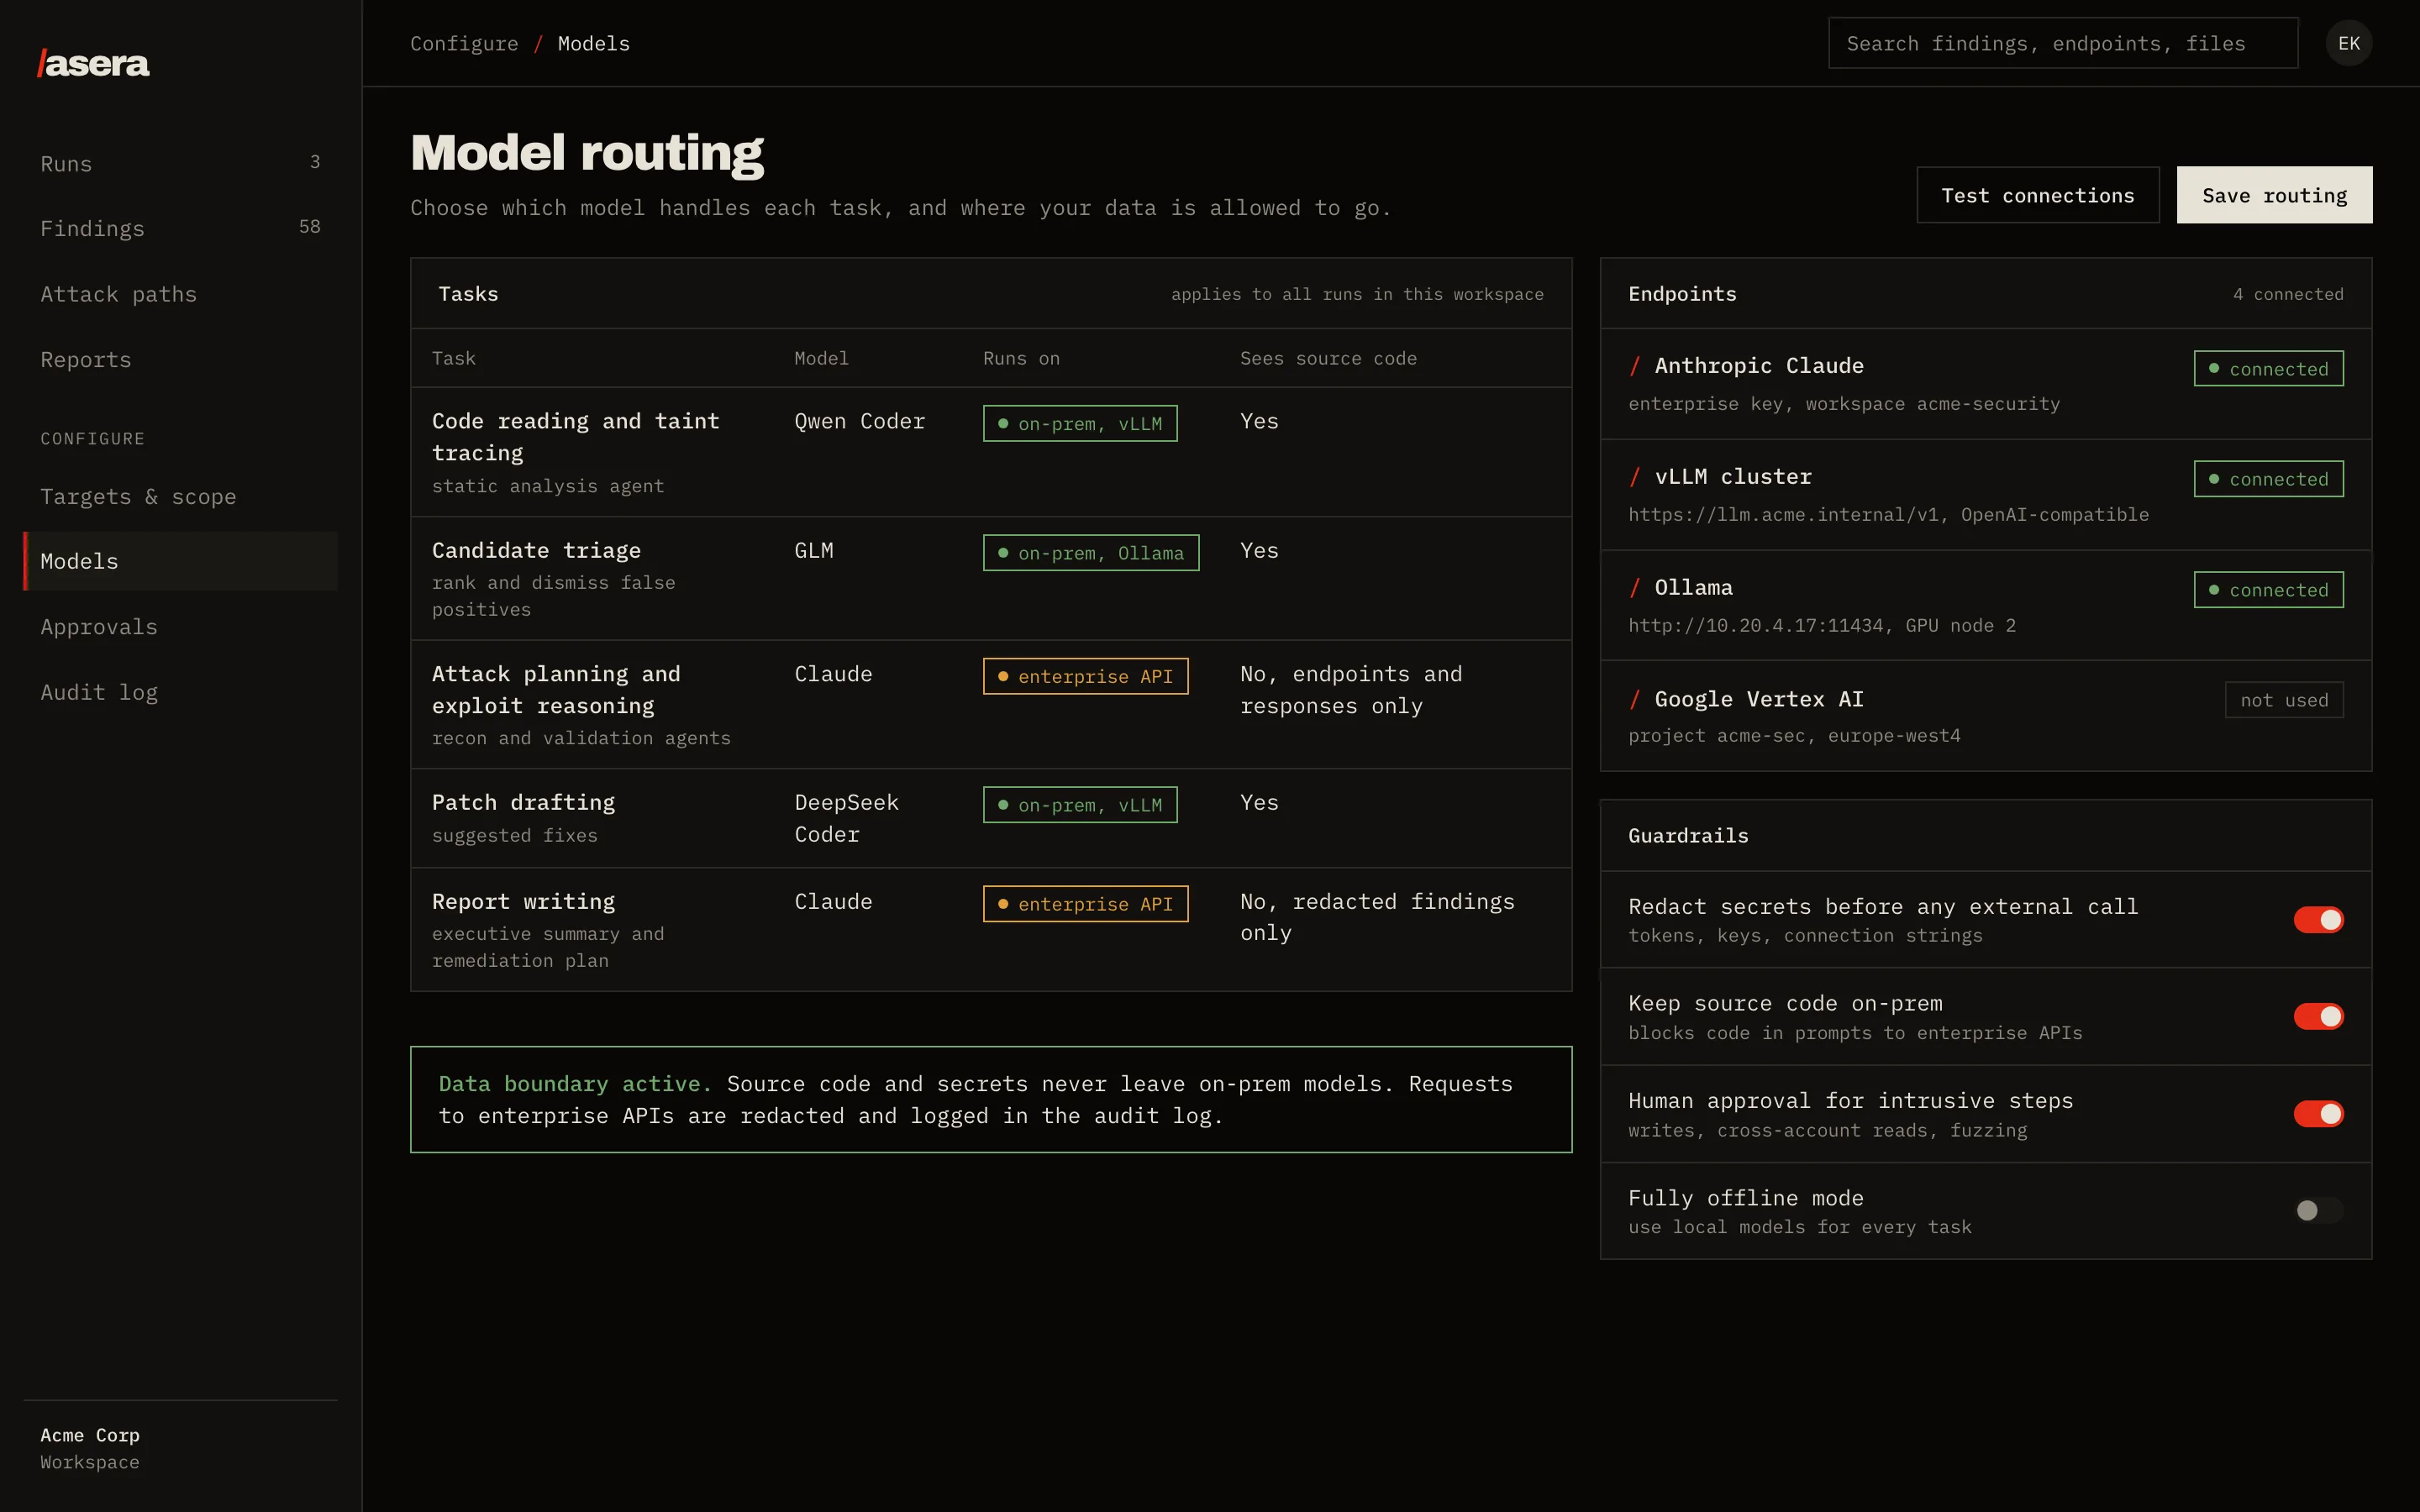
Choose the model for each task.

Keep source code on local models such as Qwen, GLM or DeepSeek, and use Claude, OpenAI or Vertex AI only where you allow it. Secrets are redacted before any external call.

  • vLLM, Ollama or any OpenAI-compatible endpoint
  • Fully offline mode
  • Every external request in the audit log
Asera model routing screen: tasks mapped to local models on vLLM and Ollama or to enterprise APIs, with data guardrails

Interface previews. All data shown is fictional.

Try Asera on your own code.

We run Asera with design partners on staging systems they own. Write to us to set up a scoped pilot.

Next: Evor, where Asera's findings get fixed